

To extract a table from a PDF, first check whether you can select the text. If you can, pull the table out with Excel ("Data → Get Data → From File → From PDF"), the free Tabula app or a Python library such as pdfplumber or Camelot. If you cannot, the file is a scan and needs text recognition (OCR) first. Then compare the row count with the PDF and make sure the prices became numbers.
The last step is the one people skip: the table "opened in Excel", so it goes straight into the store. Meanwhile rows got lost at page breaks and prices stayed text, and the error shows up only when a product sells at the wrong price. Below: how to tell the PDF type, which tool fits your situation, the four places where data breaks, and three checks that catch them.
When people search for PDF table extraction
Most often a supplier sends the price list only as a PDF, because it is easy to print and email. Someone has to move hundreds or thousands of rows into a spreadsheet or the store, so they search for "extract table from pdf", "pdf to excel" or "parse pdf". From there the paths split: a developer looks for a Python library, a store owner wants a tool that does it without code, and many ask whether ChatGPT can simply read the file.
"Which converter is best" is the secondary question. The first one is whether this is a one-off job or the supplier will send a PDF every week. That decides whether a converter is enough or you need an automatic import.
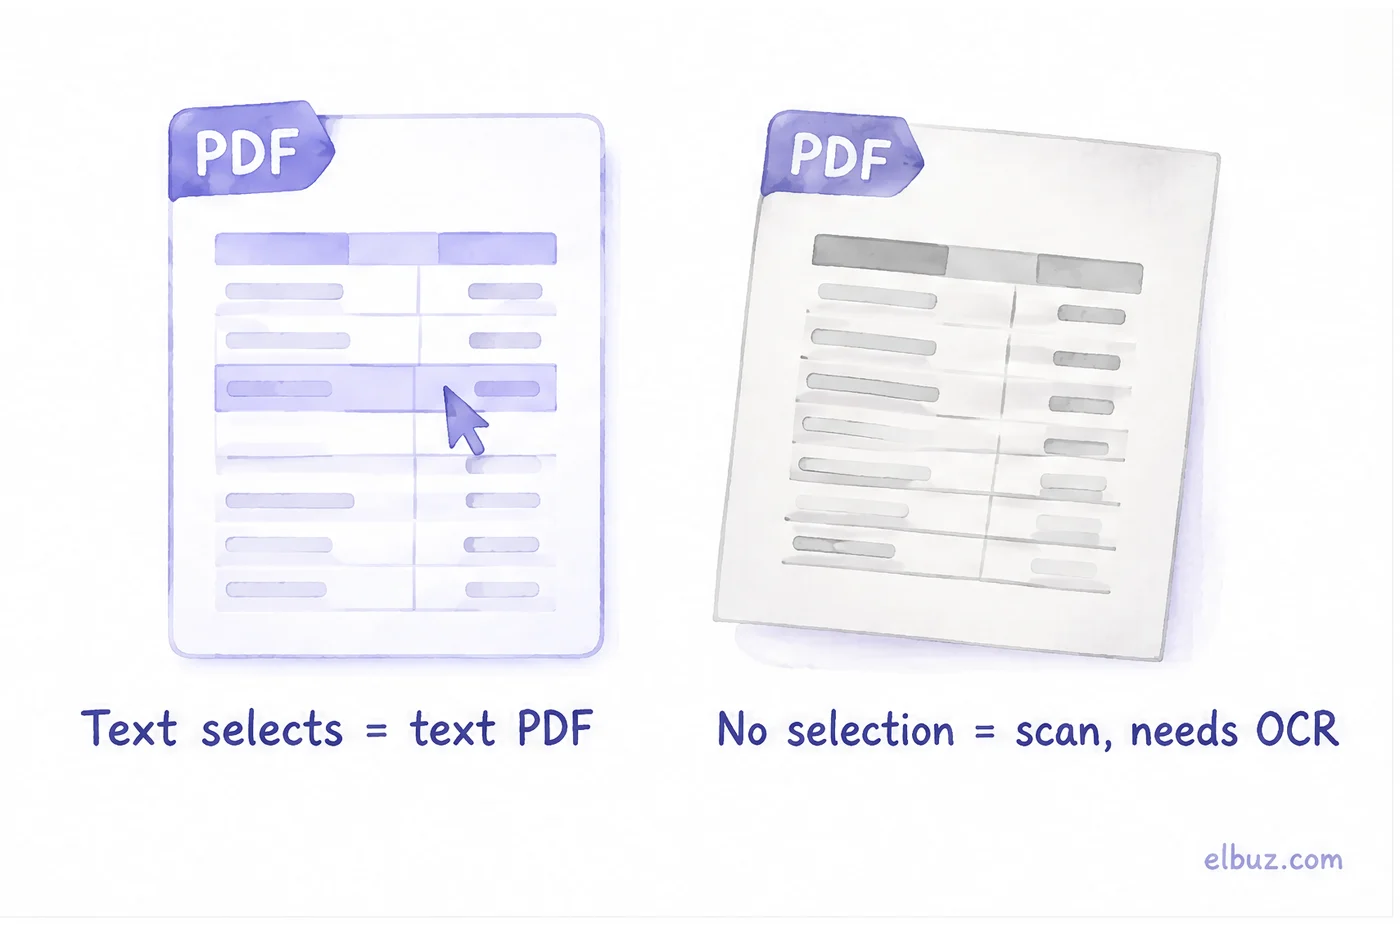
Text PDF or scan: a 10-second test
Open the file and try to select a product name or a price with the mouse. If it highlights, it is a text PDF exported from Excel or an accounting system, and the table can be extracted directly. If it does not, it is a scan or a photo of a page, and the text has to be recognised first.
Mixed files exist too: the table is text, but some pages were inserted as images. Test a few pages, not only the first one.
Which tool to use: pick by situation
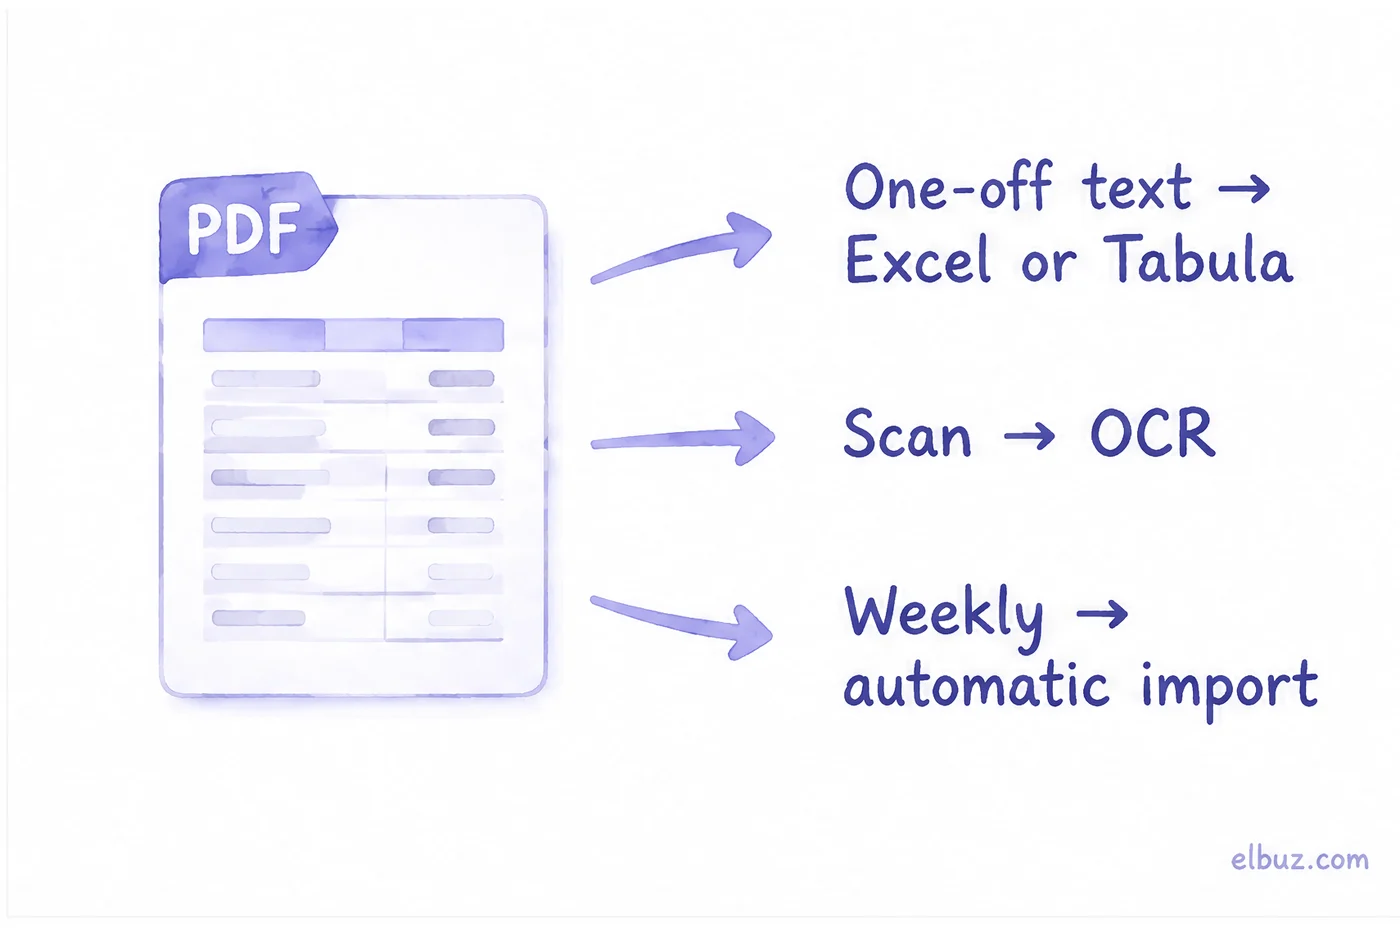
Two questions decide the tool: text or scan, and how often the file arrives. For one text price list, Excel or Tabula is enough; a scan needs OCR; a file that comes every week should be imported automatically rather than converted by hand.
| Situation | Tool | Limitation |
|---|---|---|
| One-off, text PDF, you have Excel | Excel: "Data → Get Data → From File → From PDF", then Power Query | Not available in every Excel version; multi-line rows may need cleanup |
| One-off, text PDF, no Excel | Tabula, a free app for Windows, macOS and Linux: draw a box around the table and export CSV or Excel | According to its developers, it works only on text-based PDFs, not scans |
| Many files or unusual layouts | Python: pdfplumber, Camelot | Needs a developer; pdfplumber's documentation says it works best on machine-generated PDFs, not scanned ones |
| Scan or photo | OCR, for example Tesseract, or the text recognition built into PDF editors | Accuracy depends on scan quality; check the numbers especially carefully |
| AI chat assistant | Upload the PDF and ask for a table | Convenient for a short file; nothing guarantees every row is copied exactly, so the checks below still apply |
| Same supplier every week | Ask for the same price list in Excel or CSV and set up an automatic import | Columns have to be mapped and checked once |
Online converters from the first page of search results are handy for a single file. Before uploading a price list with your purchase prices, read how the service stores files: it is your supplier's commercial information.
Where the data breaks after conversion
In four places, and none of them is visible until you look closely. A PDF does not store a table; it stores text with coordinates on the page, so every converter guesses where a row or a column ends.
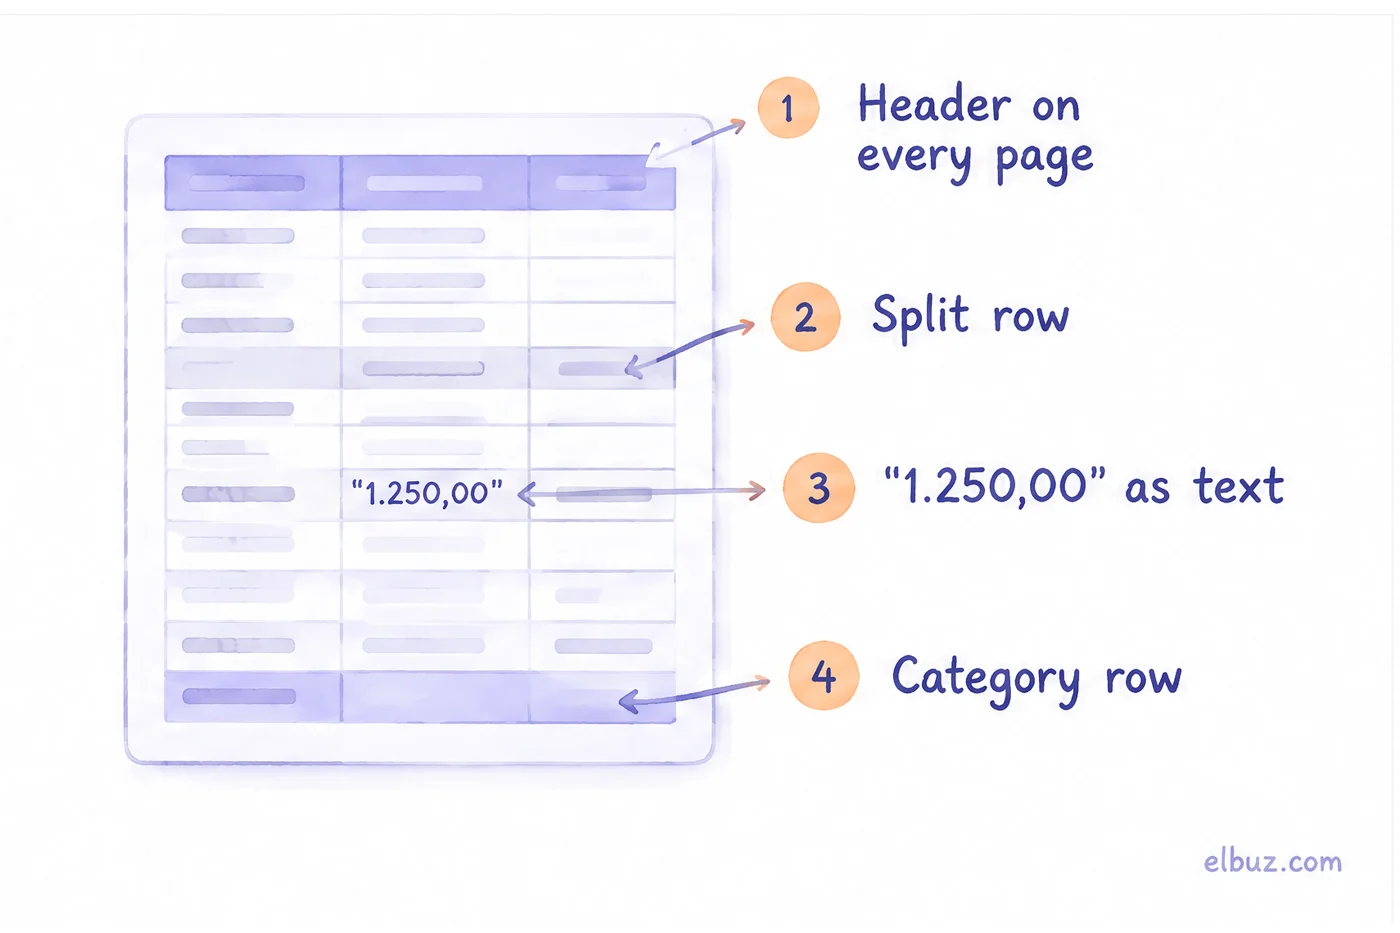
- A header on every page. Column headings repeat on each PDF page and land in the table as "products". Filter out the rows where the price column says "Price".
- A split row. A long name wraps onto a second line, and at a page break one product turns into two rows or disappears. The result is a product without a price or a price without a product.
- A price stored as text. European suppliers write "1.250,00" (dot for thousands, comma for decimals); a spreadsheet set to US number format leaves it as text, and the reverse happens with "1,250.00" in a German or French Excel. Text does not add up or take a markup, and in a store it can turn into zero.
- A category row. "Wrist watches" above a group of products becomes a separate row without a SKU. Delete it or move it into a category column.
Two more: merged cells (one price for several sizes) and a currency written once above the table. Both are fixed by hand or by an import rule.
How to check the result: three checks
Compare the row count, make sure prices are numbers, and spot-check a few products against the original. It takes a few minutes and catches almost every breakage from the previous section.
Illustrative example for the arithmetic. A price list has 31 pages with 40 products each, the last one full: 31 × 40 = 1,240 rows. After conversion and removing the repeated headers, the sheet has 1,236 rows. Four products went missing; look for them at page breaks.
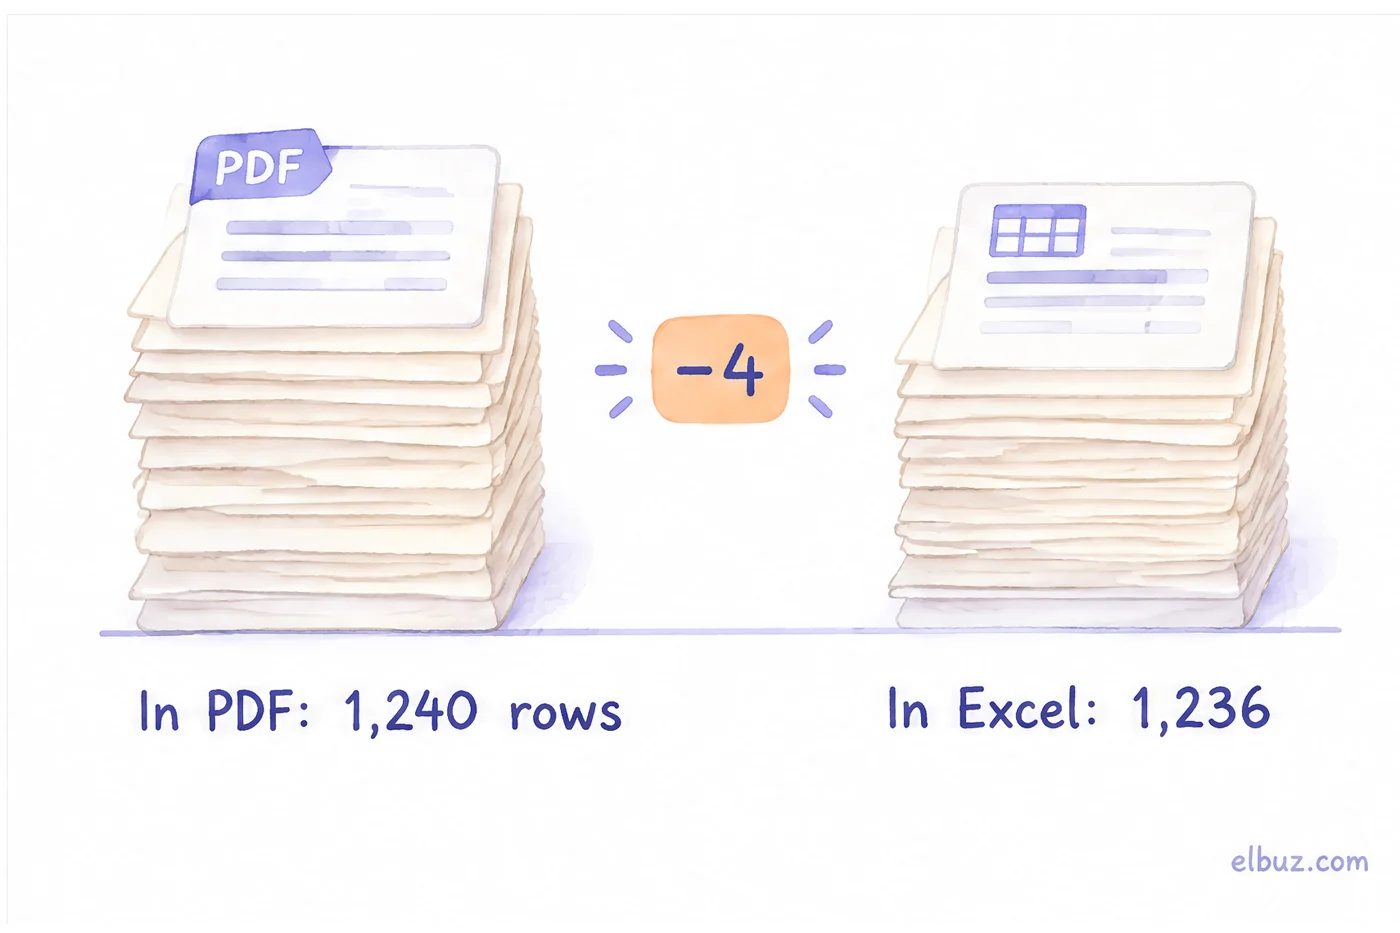
- Row count. Count the products in the PDF: by line numbers, a "Total items" line, or pages × rows. The difference is lost or split rows.
- Prices are numbers. Compare
=COUNT(C2:C1237)with=COUNTA(C2:C1237)for the price column. If the first is smaller, some prices are still text: fix the separators or the column format. - Spot check against the original. Compare 5–10 products from different pages, including the first and last row of each page: name, SKU, price and currency.
If the PDF arrives every week
Then converting by hand means the same cleanup and the same checks every week. It is better to ask the supplier once for the same price list in Excel or CSV: a PDF is almost always made from a spreadsheet, so they have it. The import maps such a file once, then puts the columns in place and recalculates prices on its own, and you only review the log.
Elbuz accepts price lists in Excel, CSV, XML and YML — as a file, by link or from email; it does not read PDF. If the supplier cannot provide a spreadsheet, convert the PDF to a table with the methods above, save it as .xlsx and upload that: from then on the file is read with the column mapping you set up once. After the first upload, check that the name, price and SKU landed in the right columns. How supplier files are processed and prices recalculated is shown on the supplier price list automation page; how retail prices are built from purchase prices, on the markup pricing page.
Ask for the supplier's spreadsheet even when a converter copes: any PDF conversion is guesswork, while a spreadsheet from the supplier already has rows and columns.
Supplier price lists in ElbuzExcel, CSV and XML on a schedule, with price recalculation
Frequently asked questions
How can I extract tables from a PDF and convert them to Excel?
In Excel, use "Data → Get Data → From File → From PDF", pick the table and load it. Without Excel, the free Tabula app does the same. Then compare the row count and the price format, see the three checks.
Is there a free way to extract tables from a PDF?
Yes. Tabula is free and works offline, and there are online converters. For a scanned file you also need OCR, for example the free Tesseract.
Which Python library is best for extracting tables from PDFs?
It depends on the layout. pdfplumber and Camelot are the usual choices for text PDFs; scans need OCR such as Tesseract before parsing. For a single file, Excel or Tabula is simpler.
Can ChatGPT pull data from a PDF?
Yes, AI chat assistants that accept file uploads can read a text PDF and return a table. For a long price list, still compare the row count and spot-check prices, because nothing guarantees every row is copied exactly.
How do I extract a table from a scanned PDF?
Run OCR first, then parse the table. Accuracy depends on the scan quality, so spot-check the numbers against the original.
Why do prices not calculate after conversion?
They are still text, usually because the thousands and decimal separators do not match your Excel number format. Fix the separators or change the column format.
Sources
- Tabula, README: "Tabula only works on text-based PDFs, not scanned documents", MIT license — github.com/tabulapdf/tabula.
- pdfplumber, README: "Works best on machine-generated, rather than scanned, PDFs" — github.com/jsvine/pdfplumber.
- Microsoft, Power Query PDF connector (Excel, multi-page tables, handling multi-line rows) — learn.microsoft.com.
- Tesseract OCR, language models — github.com/tesseract-ocr/tessdata.
Checked on October 31, 2026. All other numbers in the article are illustrative examples for the arithmetic.


